Abstract
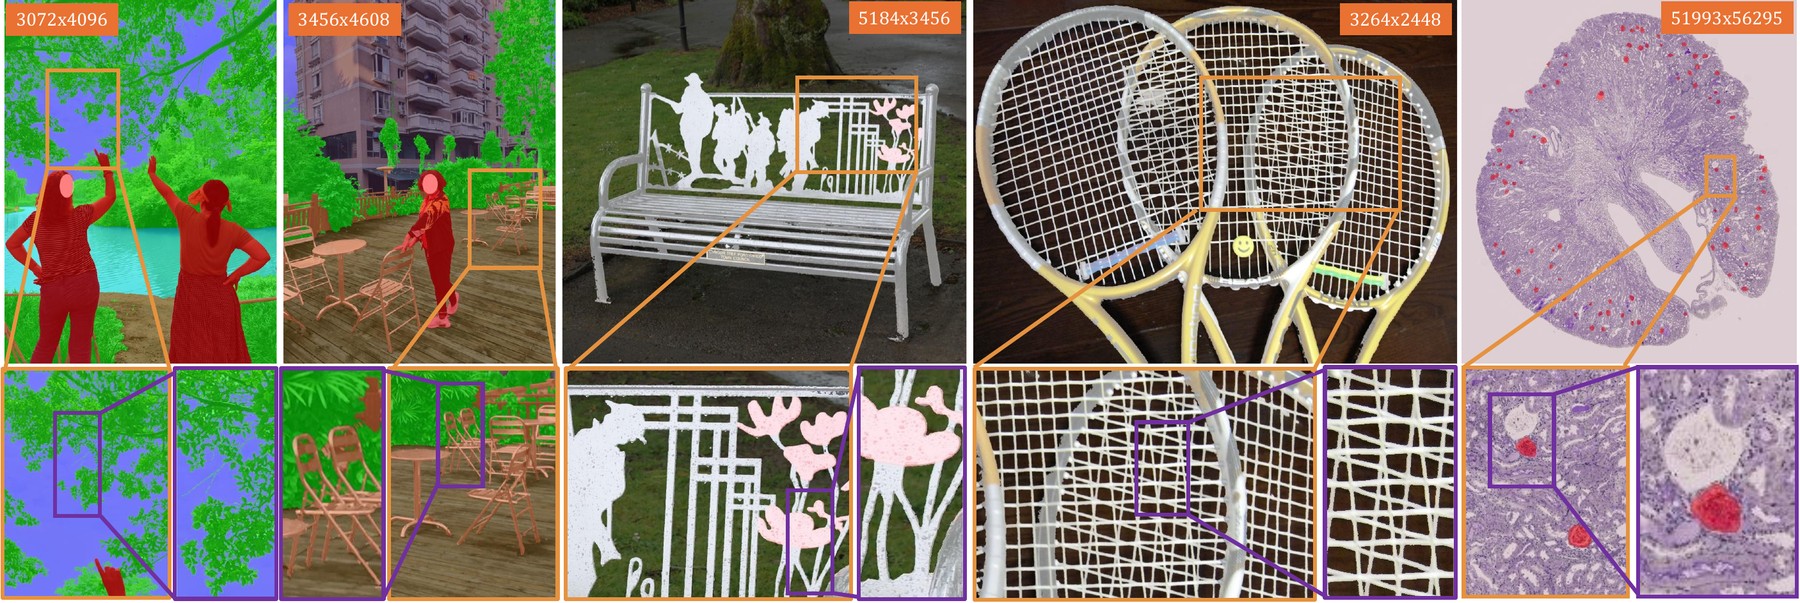
Semantic segmentation on very-high-resolution images remains challenging due to the high computational cost and the difficulty of capturing fine-grained details. We propose CoordFormer, a novel coordinate-based architecture for semantic segmentation that predicts labels at arbitrary spatial locations through a Coordinate Decoder equipped with a Localized Cross-Attention mechanism. The decoder combines coordinate embeddings with high-resolution local patch features and interacts with global tokens extracted from a downsampled image processed by a ViT foundation encoder, enabling rich semantic context while preserving pixel-level precision.
This design enables flexible inference at arbitrary resolutions while keeping memory low on very-high-resolution inputs, and supports an efficient semantic-edge-focused strategy that concentrates computation along boundaries, maintaining fine-grained accuracy while reducing latency and computational cost. CoordFormer achieves state-of-the-art performance on MaSS13K and outperforms comparably sized and higher-parameter methods on DIS5K and KPIs, demonstrating its effectiveness for high-quality, very-high-resolution semantic segmentation.
Code
Code will be released in October 2026. Training and evaluation code, along with the checkpoints used for the results in the paper, will be published in this repository. Watch it to be notified when the release lands.
Acknowledgements
We acknowledge ISCRA for awarding this project access to the LEONARDO supercomputer, owned by the EuroHPC Joint Undertaking, hosted by CINECA (Italy).
BibTeX
@article{curti2026coordformer,
  title   = {CoordFormer: Give Me Any Coordinates and I Will Give You Labels},
  author  = {Curti, Iacopo and Zama Ramirez, Pierluigi and
             Petrelli, Alioscia and Di Stefano, Luigi},
  journal = {arXiv preprint arXiv:XXXX.XXXXX},
  year    = {2026}
}